World-action models (WAMs) predict the future to act better, but they mainly predict RGB latents trained for pixel reconstruction — with no explicit signal for the 3D geometry or object semantics that manipulation needs. We introduce Flex-π, a 6B-parameter WAM that jointly denoises RGB, 3D geometry, and object-centric DINO semantics with actions in a shared latent space. Per-stream dropout with cross-modality forcing yields a single checkpoint that runs on any subset of streams — from fast action-only inference to full joint generation — with no new sensors or visual priors. The result is a demonstration-efficient policy that beats the strongest baselines by up to 2–6× on dexterous, precise, real-world bimanual tasks in and out of distribution — while running faster than π0.5.
@article{yan2026flexpi,title={Flex-π: A Multi-Stream World-Action Model with Compute Flexibility},author={Yan, Ge and Liu, Jinghao and Fan, Yuzhi and Cai, Lei and Liao, Minwen and Zhang, Jesse and Fox, Dieter},journal={arXiv preprint arXiv:2608.10860},year={2026},}
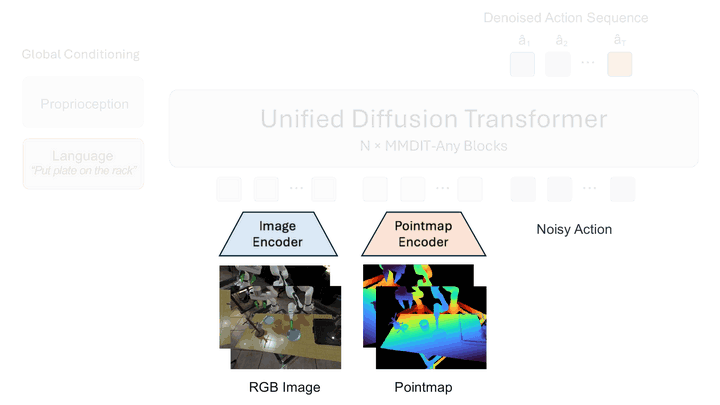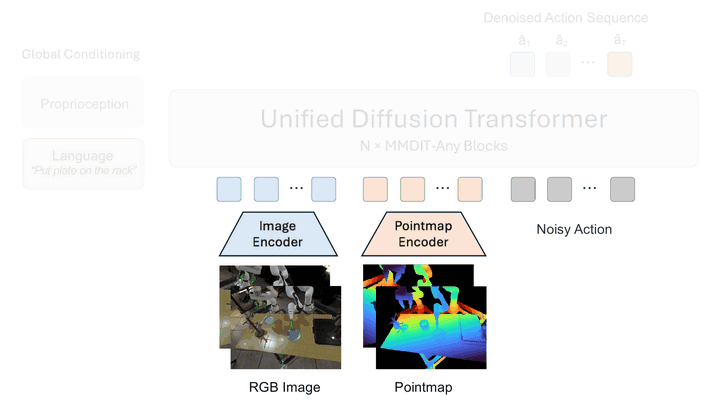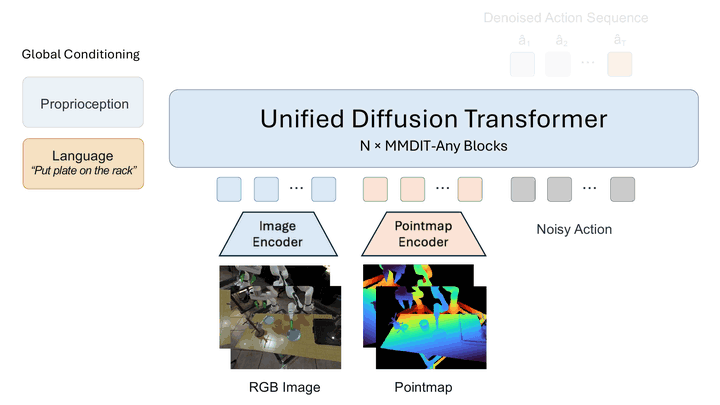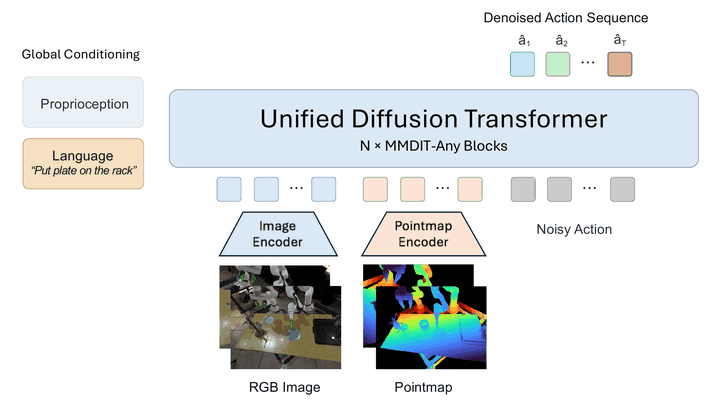
Visuomotor manipulation policies face a persistent trade-off: image-only policies inherit the semantic priors of large-scale 2D pretraining but are brittle to lighting, texture, and viewpoint shift, whereas 3D-only policies are robust to such factors yet are often trained from scratch. Some recent multi-modal policies combine both streams but typically process 3D through a from-scratch encoder, preserving this asymmetry. We present UniFlow, a unified 2D+3D co-training recipe for manipulation in which 3D observations are represented as image-shaped pointmaps so that pretrained 2D backbones can be used to encode both modalities, and RGB and pointmap streams are fused by a unified diffusion transformer with per-modality modulation. On average across thirteen dexterous manipulation tasks from the challenging LBM simulation benchmark, UniFlow outperforms a strong RGB-only baseline in a distribution-shifted setting. UniFlow also outperforms the generalist VLA when averaged over five RoboTwin bimanual tasks as well as four real-world YAM tasks.
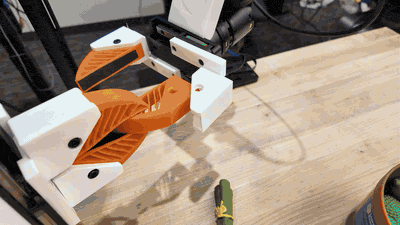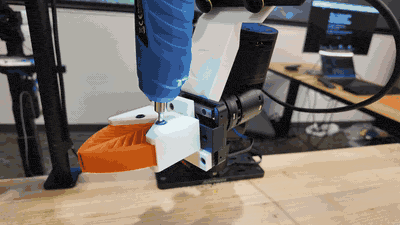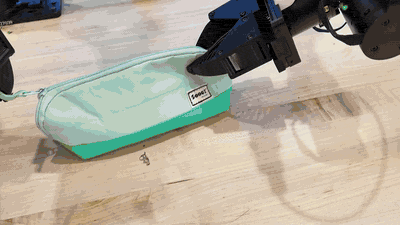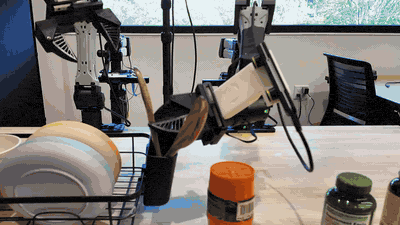 Flex-π: A Multi-Stream World-Action Model with Compute FlexibilityarXiv preprint arXiv:2608.10860, 2026